Hauptinhalt

captionImage

R2026b

Caption images using Moondream vision-language model (VLM)

Since R2026a

    Description

    Add-On Required: This feature requires the Computer Vision Toolbox Model for Moondream Vision Language Model add-on.

    captions = captionImage(mdModel,I) generates a caption for the image I using the Moondream™ vision-language model mdModel.

    captionsDS = captionImage(mdModel,imds) generates captions for the images in the image datastore imds using the Moondream vision-language model mdModel.

    [___] = captionImage(___,Name=Value) specifies options using one or more name-value arguments, in addition to any combination of arguments from previous syntaxes. For example, CaptionVerbosity="detail" specifies to return a detailed caption containing up to 60 words.

    example

    Examples

    collapse all

    Load a pretrained Moondream vision-language model with approximately 1.6 billion parameters into the workspace.

    mdModel = moondream("moondream-1.6B");

    Load an image to caption into the workspace, and display the image.

    I = imread("peppers.png");
    imshow(I)
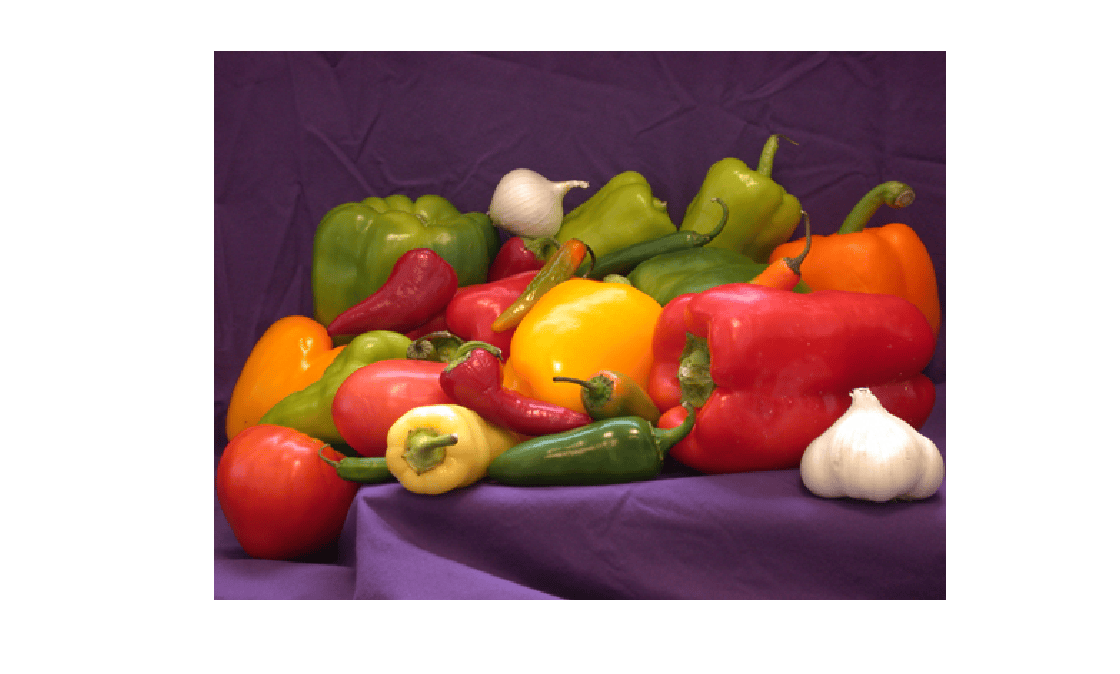
    Figure contains an axes object. The hidden axes object contains an object of type image.

    Caption the image using the captionImage object function.

    captions = captionImage(mdModel,I);

    Display the generated image caption.

    display(captions)
    captions = 
    " A purple tablecloth holds a vibrant array of red, green, yellow, and white peppers, onions, and garlic, arranged in a visually appealing composition."
    

    Load the Moondream vision-language model.

    mdModel = moondream;

    Load an image to caption into the workspace, and display the image.

    I = imread("visionteam.jpg");
    imshow(I)

    Generate a detailed caption for the image by specifying the CaptionVerbosity argument of the captionImage object function.

    captions = captionImage(mdModel,I,CaptionVerbosity="detail");

    Display the generated image caption.

    display(captions)
    captions = 
    " The image shows six individuals standing in a row in what appears to be an office setting. The individuals are dressed in a variety of casual attire, including jeans, sweaters, and sweaters. The room has a neutral color scheme with beige walls and a dark gray or black carpet. The individuals are standing in front of a large painting or artwork depicting a serene landscape. The painting is framed in a dark brown or black frame. The individuals are standing in a relatively straight line, with their arms crossed, creating a sense of unity and camaraderie."
    

    Input Arguments

    collapse all

    Moondream vision-language model, specified as a moondream object.

    Input RGB image data, specified as one of these options:

    • H-by-W-by-3 numeric array representing a single truecolor image.

    • H-by-W-by-3-by-B numeric array representing a batch of B truecolor images. B is the number of images in the batch.

    Datastore of images, specified as any type of datastore that returns image data. If calling the datastore with the read function returns a cell array, then the image data must be in the first cell.

    Name-Value Arguments

    collapse all

    Specify optional pairs of arguments as Name1=Value1,...,NameN=ValueN, where Name is the argument name and Value is the corresponding value. Name-value arguments must appear after other arguments, but the order of the pairs does not matter.

    Example: captionImage(mdModel,I,CaptionVerbosity="detail") specifies to return a caption containing up to 60 words.

    Caption length, specified as one of these options:

    • "brief" — Returns a caption containing approximately 25 words or less.

    • "detail" — Returns a caption containing up to 60 words.

    Hardware resource on which to run the model, specified as "auto", "gpu", or "cpu". The table shows the valid hardware resource values.

    Resource Action
    "auto" Use a GPU if it is available. Otherwise, use the CPU.
    "gpu" Use the GPU. To use a GPU, you must have Parallel Computing Toolbox™ and a CUDA® enabled NVIDIA® GPU. Currently, GPU execution is supported for only the pretrained Moondream vision-language model with approximately 1.6 billion parameters. If a suitable GPU is not available, the function returns an error. For information about the supported compute capabilities, see GPU Computing Requirements (Parallel Computing Toolbox).
    "cpu" Use the CPU.

    Output Arguments

    collapse all

    Image captions, returned as one of these options, depending on the format of the input image I.

    • I is a single RGB image — String scalar.

    • I is a batch of RGB images — 1-by-B string array, in which each element is the caption for the corresponding image from the batch. B is the number of images in the batch.

    Datastore image captions, returned as an N-element string array. N is the number of images in the image datastore imds.

    Tips

    • The quality of Moondream outputs can vary across different data domains. Validate its predictions using a data set from a domain similar to your intended application.

    Extended Capabilities

    expand all

    GPU Arrays
    Accelerate code by running on a graphics processing unit (GPU) using Parallel Computing Toolbox™.

    Version History

    Introduced in R2026a

    expand all