rlSARSAAgent
R2026bSARSA reinforcement learning agent
Description
The SARSA algorithm is an on-policy reinforcement learning method for environments with a discrete action space. A SARSA agent trains a Q-value function critic to estimate the value of the current epsilon-greedy policy (it does not try to directly learn an optimal policy). SARSA agents do not support recurrent neural networks.
For more information on SARSA agents, see SARSA Agent.
For more information on the different types of reinforcement learning agents, see Reinforcement Learning Agents.
Creation
Syntax
Description
Create Default Agent from Observation and Action Specifications
agent = rlSARSAAgent(observationInfo,actionInfo)
agent = rlSARSAAgent(observationInfo,actionInfo,initOpts)initOpts object. When the
agent uses a table, initOpts is ignored. SARSA agents do not
support recurrent networks. For more information on the initialization options, see
rlAgentInitializationOptions.
Create Agent from Critic
agent = rlSARSAAgent(critic,agentOptions)AgentOptions
property.
Input Arguments
Properties
Object Functions
train | Train reinforcement learning agents within a specified environment |
sim | Simulate trained reinforcement learning agents within specified environment |
getAction | Obtain action from agent, actor, or policy object given environment observations |
getCritic | Extract critic from reinforcement learning agent |
setCritic | Set critic of reinforcement learning agent |
generatePolicyFunction | Generate MATLAB function that evaluates policy of an agent or policy object |
Examples
Create or load an environment object with a discrete action space. For this example, use the same environment as in the example Train Reinforcement Learning Agent in Basic Grid World.
env = rlPredefinedEnv("BasicGridWorld");Get the observation and action specifications.
obsInfo = getObservationInfo(env);
actInfo = getActionInfo(env);
Create a Q-learning agent using the specifications.
agent = rlSARSAAgent(obsInfo,actInfo)
agent =
  rlSARSAAgent with properties:

            AgentOptions: [1×1 rl.option.rlSARSAAgentOptions]
    UseExplorationPolicy: 0
         ObservationInfo: [1×1 rl.util.rlFiniteSetSpec]
              ActionInfo: [1×1 rl.util.rlFiniteSetSpec]
              SampleTime: 1
Because the observation is a single discrete channel, the agent's critic uses a table as approximation model.
getModel(getCritic(agent))
ans =
  rlTable with properties:

    Table: [25×4 double]
Specify an Epsilon value of 0.2.
agent.AgentOptions.EpsilonGreedyExploration.Epsilon = 0.2;
To check your agent, use the getAction function to return the action from a batch of 10 random observations.
act = getAction(agent,{randi(numel(obsInfo.Elements),[obsInfo.Dimension(1) 10])});Display the seventh element in the batch.
a = act{1}(7)a = 1
To find the action label corresponding to the numerical index, use the idx2action function.
idx2action(env.Model,a)
ans =
"N"
The action represents an attempt to move north.
You can now test and train the agent against the environment.
Create an environment with a discrete action space, and obtain its observation and action specifications.
For this example, load the environment used in the example Create DQN Agent Using Deep Network Designer and Train Using Image Observations. This environment has two observation channels: one carrying a 50-by-50 grayscale image and the other carrying a scalar (the angular velocity of the pendulum). The action is a scalar with five possible elements (a torque of either -2, -1, 0, 1, or 2 Nm applied to a swinging pole).
% Load predefined environment.
env = rlPredefinedEnv("SimplePendulumWithImage-Discrete");

% Obtain observation and action specifications.
obsInfo = getObservationInfo(env);
actInfo = getActionInfo(env);
Create an agent initialization option object, specifying that each hidden fully connected layer in the network must have 128 neurons (instead of the default number, 256).
initOpts = rlAgentInitializationOptions(NumHiddenUnit=128);
The agent creation function initializes the actor and critic networks randomly. To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")Create a default SARSA agent from the environment observation and action specifications. Pass the initialization options object as the third argument.
agent = rlSARSAAgent(obsInfo,actInfo,initOpts);
Extract the deep neural network from both the critic.
criticNet = getModel(getCritic(agent));
To verify that each hidden fully connected layer has 128 neurons, you can display the layers on the MATLAB® command window,
criticNet.Layers
or visualize the structure interactively using analyzeNetwork.
analyzeNetwork(criticNet)
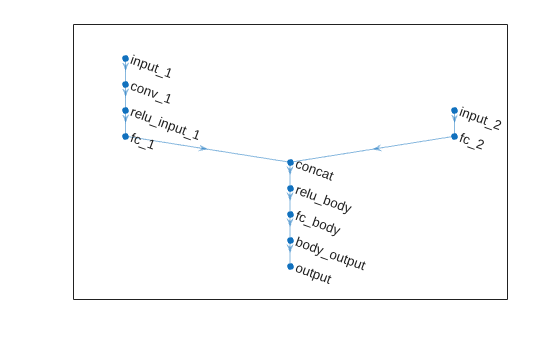
Plot the critic network.
plot(criticNet)
To check your agent, use the getAction function to return the actions from a batch of 10 random observations.
obs1 = rand([obsInfo(1).Dimension 10]);
obs2 = rand([obsInfo(2).Dimension 10]);
act = getAction(agent,{obs1,obs2});
Display the seventh element in the batch.
act{1}(7)ans = -1
You can now test and train the agent within the environment.
Create or load an environment object with a discrete action space. For this example load the Basic Grid World environment object also used in the example Train Reinforcement Learning Agent in Basic Grid World.
env = rlPredefinedEnv("BasicGridWorld");Get the observation and action specifications.
obsInfo = getObservationInfo(env);
actInfo = getActionInfo(env);
A SARSA agent uses a parameterized Q-value function to estimate the value of the policy. A Q-value function takes the current observation and an action as inputs and returns a single scalar as output (the estimated discounted cumulative long-term reward for taking the action from the state corresponding to the current observation, and following the policy thereafter).
Because in this example both the observation and action spaces are discrete and low-dimensional, use a table to model the Q-value function within the critic. rlTable creates a value table object from the observation and action specifications objects.
Create a table approximation model derived from the environment observation and action specifications.
qTable = rlTable(obsInfo,actInfo);
Create the Q-value function approximator object using qTable and the environment specification objects. For more information, see rlQValueFunction.
critic = rlQValueFunction(qTable,obsInfo,actInfo);
Create a SARSA agent using the approximator object.
agent = rlSARSAAgent(critic)
agent =
  rlSARSAAgent with properties:

            AgentOptions: [1×1 rl.option.rlSARSAAgentOptions]
    UseExplorationPolicy: 0
         ObservationInfo: [1×1 rl.util.rlFiniteSetSpec]
              ActionInfo: [1×1 rl.util.rlFiniteSetSpec]
              SampleTime: 1
Specify an Epsilon value of 0.2.
agent.AgentOptions.EpsilonGreedyExploration.Epsilon = 0.2;
To check your agent, use the getAction function to return the action from a batch of 10 random observations.
act = getAction(agent,{randi(numel(obsInfo.Elements),[obsInfo.Dimension(1) 10])});Display the seventh element in the batch.
a = act{1}(7)a = 1
To find the action label corresponding to the numerical index, use the idx2action function.
idx2action(env.Model,a)
ans =
"N"
The action represents an attempt to move north.
You can now test and train the agent against the environment.
Version History
Introduced in R2019a
See Also
Functions
getAction|getActor|getCritic|getModel|generatePolicyFunction|generatePolicyBlock|getActionInfo|getObservationInfo
Objects
rlSARSAAgentOptions|rlVectorQValueFunction|rlQValueFunction|rlQAgent|rlLSPIAgent|rlDQNAgent

